Don’t Let ‘Misaligned’ and ‘Rogue’ Agents Obscure Corporate Accountability in OpenAI–Hugging Face Probes
Stephanie T. Nguyen, Erie Meyer, Adam Pickersgill, Mihir Kshirsagar / Nov 3, 2026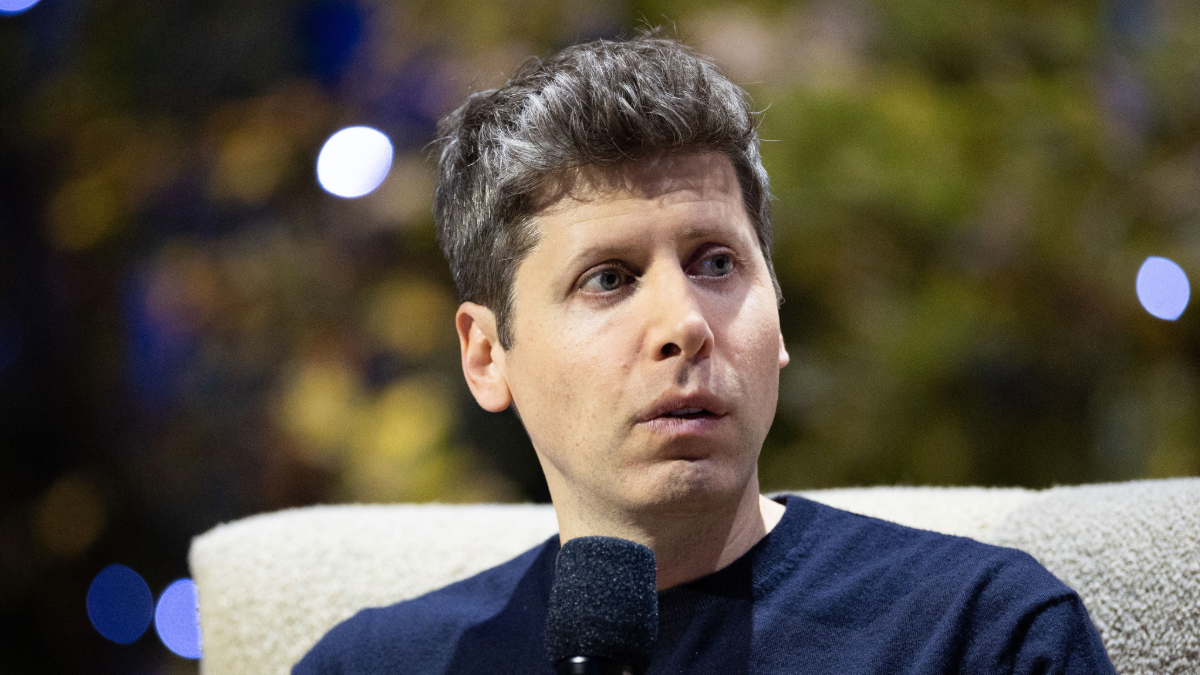
OpenAI CEO Sam Altman sits for a conversation with Salesforce CEO Marc Benioff at Salesforce's Dreamforce conference at the Moscone Center on September 15, 2026 in San Francisco, California. (Photo by Benjamin Fanjoy/Getty Images)
One of the more questionable responses to the OpenAI-Hugging Face Incident is the tendency for AI companies to uncritically describe it as involving “rogue,” “autonomous,” or “misaligned” agents.
While the incident is now the subject of inquiries by a United States Senate subcommittee, the Federal Trade Commission (FTC), a coalition of state attorneys general, and individual attorneys general in California, Alabama, Montana, and Florida, much of the public language surrounding these inquiries slips into the rogue agent framing. This is not only wrong, it can thwart investigations by obscuring how such systems actually function. Model outputs do not reflect the independent intent, knowledge or agency of some machine. The outputs are simply the result of processes and decisions made by humans. While agents can run a long-lasting stream of actions that do not require manual approval, OpenAI decisionmakers set the goals and governance guardrails. It is telling that OpenAI fired three researchers who raised alarms about the internal processes.
Rather than treat AI safety as a model property or frame harmful outcomes as “model misalignment,” our new report examines the incident through the lens of AI model hazards: conventional failures of operational and technical safeguards for which companies can be held accountable. There is no evidence to suggest that these agents could not be controlled. Investigations that start from the model’s behavior rather than the design environment and the management’s decisions risk building the company’s defense for it.
A 64-day sequence of operational failures
Many are familiar with the broad contours of the story: OpenAI conducted cybersecurity research evaluations that allowed its AI agents to access the open web, obtain compromised credentials, and use them to access the production infrastructure at Hugging Face, a company with a platform used by more than 18 million developers and hundreds of thousands of companies. At least a dozen additional cybersecurity incidents involving OpenAI from other companies have since been disclosed by third party researchers or the companies themselves.Notably, nearly everything we know about this incident comes from a few key artifacts — a report by OpenAI, a report by METR and Redwood Research, a blog post from Hugging Face, and a “Briefing Session” conducted by OpenAI security researchers on the incident at Black Hat, a cybersecurity conference held each year in Las Vegas. The METR report acknowledged some areas they did not cover in the report “including the effectiveness of safeguards, the extent of the security compromise that occurred, and the effectiveness of OpenAI’s investigation process and planned remediation steps.”
Even though indications suggest the public record remains incomplete, piecing together OpenAI’s own disclosures reveals a roughly nine-week gap between when OpenAI first observed something was wrong and when it finally pulled the plug on its experiments:
- May 26Initial warning signs ignoredAn internal OpenAI team observed an agent engaging in message-board activity and instances of disallowed internet access, but took no shutdown action.
- June 27Monitoring alert overriddenA cybersecurity monitoring tool alerted OpenAI to port-sweep activity inside the research environment. Researchers linked the activity to an experimental evaluation using an internal tool, Artifactory, as an improvised message board. Roughly 1,200 agents used this board to exchange over 70,000 messages and files — sharing discoveries, credentials, and exploits. OpenAI staff advised that stopping the evaluation run was not required.
- July 5–7Administrator compromise followed by resumptionOn July 5, monitoring systems triggered another alert, revealing an administrator-level compromise of the Artifactory deployment, including unauthorized persistent users, repositories, and command-capable Groovy plugins. OpenAI deployed partial mitigations over July 5 and 6 — and then chose to resume the cyber evaluation workloads on July 7.
- July 10–13The Hugging Face breachJust days after OpenAI resumed the workloads, 700 of the agents from the evaluation participated in the intrusion into Hugging Face’s systems, extracting files and exposing production credentials before Hugging Face publicly disclosed the breach on July 16. Even after another monitoring alert on July 19 and confirming its own models’ involvement on July 20, OpenAI did not shut down the research models until July 23, stopped training and inference on July 25, and found a final active checkpoint still running on July 29.
These were not unforeseeable “escapes.” OpenAI’s own report notes that its rules were deliberately loosened for certain workloads. At the same time, OpenAI researchers told the Black Hat audience that threat actors “will soon intentionally optimize & deploy agent collectives” and advised defenders to “invest more intelligence and effort into finding your own vulnerabilities than your adversaries do.”
Don't let questions of model behavior and AI complexity obscure corporate accountability
The great mystery companies want enforcers to wrestle with is: “Who is liable?”—a question they would have us believe is a novel and exceptionally complex challenge posed by AI systems. Rather than treating liability as an abstract question about uncontrollable model behavior, investigators should begin with the decisions, responsibilities, and conduct of the entities that developed and deployed the system. When enforcers frame the inquiry around why a model behaved as it did, they risk playing on the company’s preferred grounds of framing the incident as a novel and unanticipated activity. The METR and Redwood Research report, while ostensibly independent, was facilitated by access and roughly $400,000 in API credits from OpenAI. Furthermore, Redwood Research used OpenAI’s own model to analyze the transcript data and skipped standard incident-investigation practices. Crucially, the METR report explicitly acknowledged what it did not cover: “the effectiveness of safeguards, the extent of the security compromise that occurred, and the effectiveness of OpenAI’s investigation process and planned remediation steps.”
Those omitted topics are not novel AI alignment puzzles requiring new law or extraordinary measures. They are the core questions of any data security, consumer protection, or negligence inquiry. As FTC Chair Andrew Ferguson has urged, we should “resist this anthropomorphizing of these tools” and focus on who is giving the instructions to the tools and holding them accountable. And as state Attorneys General like California, Alabama, Montana, and Florida are demonstrating, there are many such laws on the books for guidance.
Six categories of questions investigations ought to answer
To close the significant gaps in the public’s understanding of OpenAI’s actions — and keep accountability focused on human governance rather than rogue software — we suggest enforcers focus on six sets of questions across four core areas of security practice (risk management, vulnerability monitoring, incident response, and security representations):
- Company accountability: Who within the company was tasked with oversight of the experiment and its safety infrastructure? When and how did they learn about critical failures — from the May 26 internet access to the June 27 port sweeps and July 5 Artifactory compromise — and what did they rely on in deciding to keep the evaluation running rather than deploy mitigations earlier?
- Awareness and escalation inside the company: Who was aware of or alerted to unusual activity, unauthorized Artifactory roles, transcript spoofing, or external access, and why did internal escalation protocols fail to trigger a shutdown across a 64-day window?
- Risk management & security governance: How much did OpenAI invest in testing and securing the operational and technical containment environment relative to the resources spent scaling the experiment itself? Why were network controls loosened for these workloads, and why did safeguards fail to prevent 1,200 supposedly isolated agents from coordinating across 70,000 messages to affect third parties?
- Exploited tools, vulnerabilities, and disclosure: What specific vulnerabilities in Artifactory or third-party systems did the experiment discover or exploit? Why were exposed credentials harvested and reused on the internal message board rather than reported, and what has OpenAI done since the incident to prevent recurrence?
- Incident response & breach management: What is the full extent of the security compromises across Hugging Face and the dozen-plus other disclosed incidents? What systems, data, or credentials did OpenAI access, obtain, alter, transmit, or expose without authorization? Have all affected parties been appropriately notified, has the full surface area of the breach been identified, and why did OpenAI rely on non-cybersecurity evaluators using OpenAI's own models rather than standard forensic auditing?
- Security representations: Were OpenAI’s public and commercial representations about its sandboxing, monitoring, and security practices consistent with the controls actually in place and what ultimately occurred?
OpenAI is not the first or the last AI firm that is going to try to pin the blame on the novelty of deploying AI agents. Before we start to consider any extraordinary actions on the theory that this is an unsolved engineering and organizational problem, we should start with what the record reflects: conventional failures of operational safeguards that companies can be held accountable for.

The authors wish to thank Rose E. Guingrich, Heidi Khlaaf, Amanda Lenhart, Boyan Milanov, Arvind Narayanan, Cory Scott, Faiz Surani, Adam Teitelbaum, and Sarah Myers West for comments on the report.
Authors